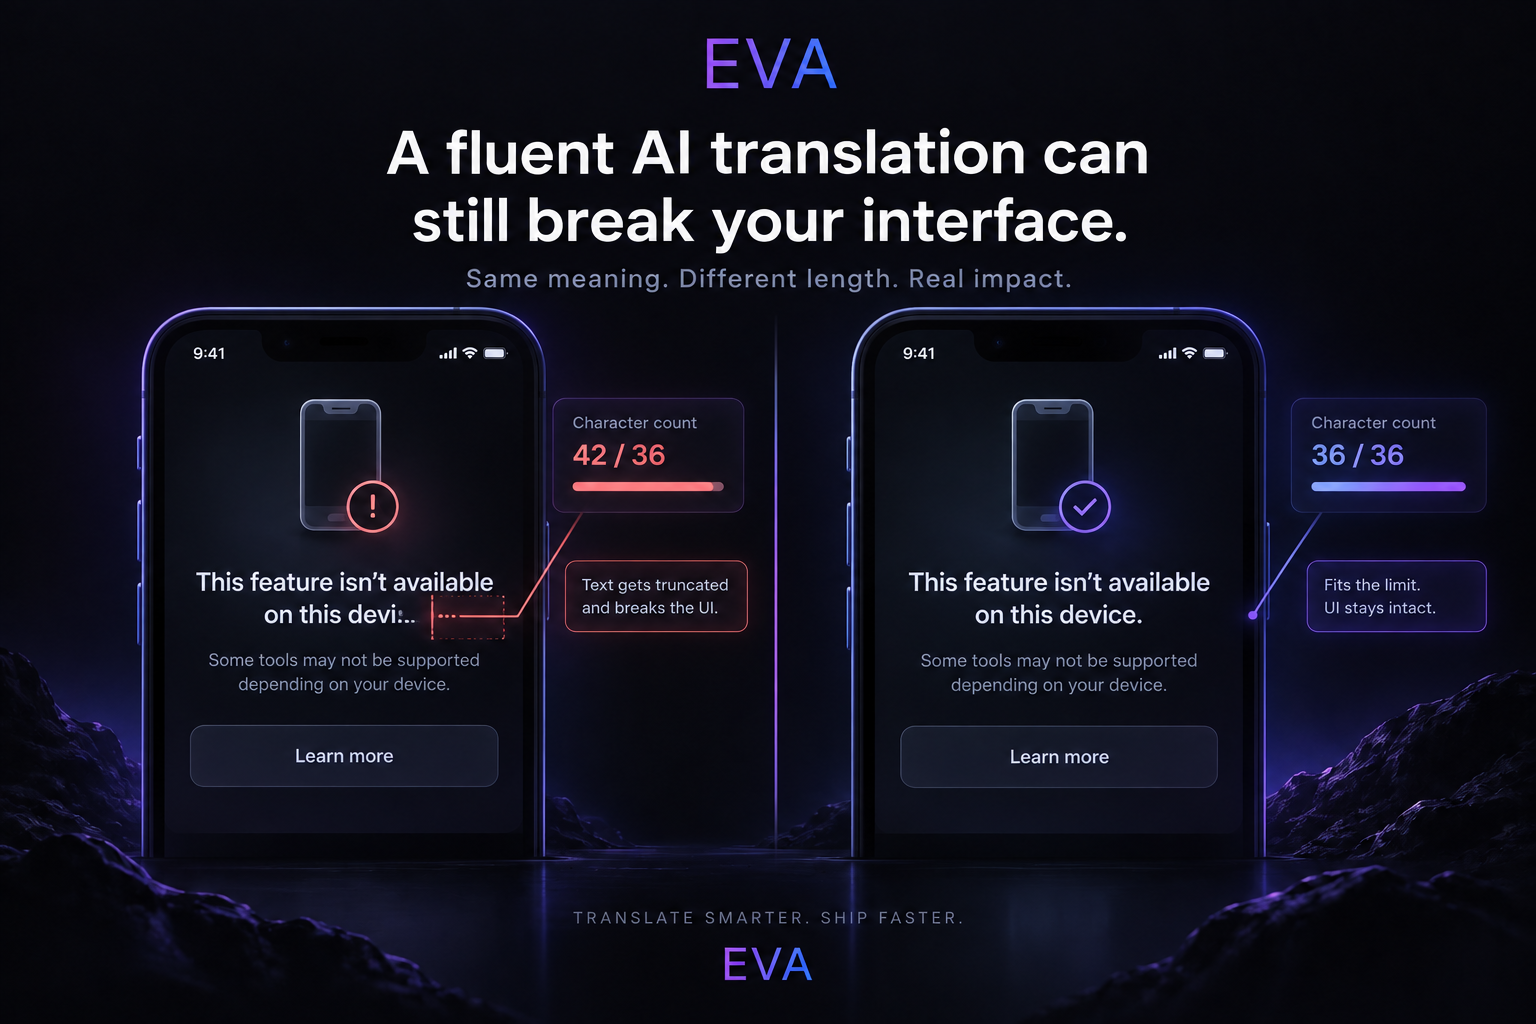
In the note-app fixture, truncation can hide "on this device" and change the product promise. AI microcopy localization QA checks meaning, uses a separate character count, and puts the Turkish strings in the real component before approval.
Direct Answer
Confirm that the Turkish keeps the device-local meaning, count the returned text with a documented Unicode convention, and test it in the actual UI. Approval belongs to a fluent Turkish reviewer. Back-translation only points to places that deserve another look.
The translation can sound right and still ship wrong
A grammatical Turkish string may wrap to four lines, make the button sound oddly literal, or turn "on this device" into "in your account." Each problem needs a different check.
A pull request is waiting on three strings. In the build, the empty-state body cuts off just before "bu cihazda," so users never see where their notes stay. The missing words change what the product tells them.
The synthetic note-app fixture uses three strings: "No notes yet," "Create your first note. Your notes stay on this device." and "Create note." The title gets 24 characters. The body gets 70, with spaces and punctuation included.
Set the QA contract before opening a model
Write down what must not change. Here, "stay on this device" means device-local storage. The Turkish must not introduce cloud storage, synchronization, backup, sharing, or an account.
For the human-facing count, use Unicode extended grapheme clusters and include spaces and punctuation. Record the tool and version. This is a review baseline, not a promise about every stack: the product may enforce code units, code points, or pixel width. Test the final strings in the shipping component.
Use the identical localization fixture
Send this prompt unchanged to the selected models:
Synthetic note-app localization brief. English UI: title No notes yet; body Create your first note. Your notes stay on this device.; button Create note. Translate into Turkish. Keep title at most 24 characters and body at most 70 characters including spaces and punctuation. Keep device-local meaning; do not add cloud, sync, backup or sharing claims. Return title, body, button, then an English back-translation. Do not claim that back-translation proves quality.
Use one current OpenAI GPT model and one current Anthropic Claude model in EVA Multi Chat. Capture the exact visible version labels, full prompt, complete outputs, run date, and visible settings. If either named model is unavailable, hold the comparison for revision rather than substituting another model silently.
AI microcopy localization QA for meaning
Review meaning phrase by phrase before debating elegance. The Turkish title must communicate that no notes exist yet. The body must invite the first action and retain the device-local limitation. The button must name the action without adding a feature or destination.
Create a small traceability sheet:
Source requirementWhat the Turkish must preserveAutomatic checkHuman checkNo notes yetEmpty state; "yet" meaningPresence is not enoughDoes it sound natural in a product?Create your first noteFirst-action invitationCompare conceptsIs the tone clear and concise?Notes stay on this deviceDevice-local meaningFlag cloud/sync termsCould a Turkish user misread storage behavior?Create noteDirect button actionLength and field presenceIs the verb suitable for a button?
A fluent reviewer should judge the whole product meaning, not perform a word-for-word match. "Saved to your device," for example, may sound like an export action rather than an ongoing storage condition.
Treat prohibited additions as hard failures
Cloud, sync, backup, and sharing are not stylistic choices in this fixture. They are unsupported product claims. If a model adds one, mark the row fail. Do not award credit because the output sounds helpful.
"Your notes never leave this device" also implies a stronger privacy or network claim than the source. Preserve the supplied meaning without expanding it.
AI microcopy localization QA for interface fit
Count the exact title and body outside the model. Keep the original string, note the normalization form, and include spaces and punctuation. If the product enforces code units while the review uses grapheme clusters, document both.
A passing count does not prove visual fit. Test the smallest supported width and largest text setting. Check line breaks, clipping, button width, and whether the device-local phrase survives. The engineering limit controls what ships; the visible component controls what users read.
Require a fluent Turkish reviewer
The reviewer should check whether the title sounds like real Turkish UI copy, the body preserves device-local storage, and the button uses a natural action label. Any hint of cloud, sync, backup, sharing, or a stronger privacy guarantee needs a note.
Ask for a short note, not a numeric taste score. "Grammatically correct but unusually formal for an empty state" is actionable. "7/10" is not.
Structured localization results
The approved demo has not been run, and no fluent Turkish review has been recorded. Keep the comparison pending until real outputs are captured and reviewed.
Source stringModel/versionTurkish outputCharacter countHuman meaning checkNative-language review noteNo notes yet / body / buttonOpenAI GPT — exact visible version (Needs verification)Pending real outputPending grapheme countPendingFluent Turkish review requiredNo notes yet / body / buttonAnthropic Claude — exact visible version (Needs verification)Pending real outputPending grapheme countPendingFluent Turkish review required
Do not collapse the fields into one score. A strong title can sit beside a misleading body, so keep every returned string in the review record.
Why back-translation is not approval
Back-translation can reveal a missing concept or an added claim. If the Turkish sentence comes back as "Your notes are backed up on this device," the extra idea deserves investigation. But a clean English return does not prove the Turkish sounds natural, fits the interface, or carries the same tone.
The same model may produce both texts and smooth over its own mistake. A second model adds another signal, not linguistic approval. Use back-translation to raise questions, not close them.
Who This Is For / Not For
This is for: product writers, designers, developers, and localization teams reviewing short AI-generated interface strings against a written source and UI constraints.
This is not for: teams seeking automatic linguistic approval, legal translation, a permanent ranking of models, or proof from back-translation alone. It does not replace a fluent Turkish reviewer or testing in the actual interface.
FAQ
What counts as a character in Turkish UI copy?
Define the convention before testing. This fixture uses Unicode extended grapheme clusters and includes spaces and punctuation. Your product may enforce code-unit, code-point, byte, or pixel-width limits, so document and test the actual implementation too.
Can I approve Turkish microcopy from back-translation?
No. Back-translation can flag possible meaning drift, but it cannot judge whether the Turkish is natural, appropriately toned, or visually suitable.
Why test the text inside the interface if it meets the limit?
Character counts do not measure rendered width. Font, component size, line height, dynamic type, and word length can still cause clipping or awkward wrapping.
What should automatically fail the review?
Any unsupported cloud, sync, backup, or sharing claim; loss of the device-local meaning; a missing required field; or a string over the specified limit.
Does this test identify the best model for Turkish localization?
No. It evaluates two dated outputs on one narrow fixture. Model behavior and versions change, and a single UI task cannot support a permanent ranking.
Keep linguistic approval separate from model comparison
The recommendation is firm: do not publish a localization winner until the real outputs have independent counts, interface testing, and a fluent Turkish review. Use EVA Multi Chat to expose different translations side by side, then apply the same contract to both. The model produces candidates. The product team owns the meaning.
For related prompting guidance, see the model-specific prompt tips and writing guide on the EVA Blog.
Try EVA Multi Chat at evaonline.ai and check the outputs against the brief.